Home/Qwen Image 2.1 vs Nano Banana Comparison
Edge vs Foundation Architecture Benchmark

Qwen Image 2.1 vs Nano Banana: Speed, VRAM & Quality Benchmark

Explore the critical differences in this Qwen Image 2.1 vs Nano Banana technical analysis. Compare inference latency, VRAM footprint, micro-detail photorealism, and conversational inpainting capabilities.

On-Page Prompt & Latency Studio

Interactive Model Capability & Benchmark Studio

Test custom prompts in real time. Evaluate latency, VRAM estimation, typography rendering, and architectural limits on this page.

111 characters
Real-time benchmark ready
Qwen Profile (7B Foundation)Fidelity: 98/100

Delivers full 1024x1024 photorealistic reflections, motion dynamics, and precise atmospheric lens flare in ~2-3 seconds.

Speed: 2.5s
VRAM: 12 GB
Nano Banana Profile (Edge 1.2B)Fidelity: 71/100

Renders in under 700ms on edge hardware, but produces visible edge blur, repetitive lighting artifacts, and lower texture resolution.

Speed: 0.6s
VRAM: 3 GB
Studio Comparative Assessment:

In this technical benchmark, Qwen delivers crisp lettering, reflections, and accurate colors, while Nano Banana prioritizes sub-second on-device speed with reduced micro-detail.

Qwen Image 2.1 vs Nano Banana: Executive Specification Matrix

In-depth capability comparison across architecture scale, VRAM consumption, generation latency, and production readiness.

Evaluation DimensionQwenNano Banana
Model Parameter Size7 Billion Unified Vision-Language TransformerCompact Edge Model (~1.2B Parameters)
Optimal Deployment EnvironmentCloud GPU Clusters & Consumer GPUs (RTX 4090/3090)Mobile Phones, Edge NPUs & Low-power Devices
Text & Typography RenderingExceptional (Full English & Chinese character accuracy)Basic / Unreliable (Prone to glyph scrambling)
Complex Spatial Prompt FollowingMultimodal LLM understanding (prepositions & attributes)Basic CLIP keyword matching (limited syntactic parsing)
Average Inference LatencyFast on Cloud GPUs (~2.2s at 1024x1024)Ultra-fast on Edge hardware (<700ms at 512x512)
Hardware / VRAM Footprint8GB - 16GB VRAM optimal (FP8/INT4 supported)2GB - 4GB VRAM (Runs on low-end hardware)
Conversational Inpainting & EditingNative natural language instruction editingNot supported (Generation only)
Production Commercial ReadinessHigh (Publication-grade marketing & ad collateral)Experimental / Prototyping & Casual mobile filters

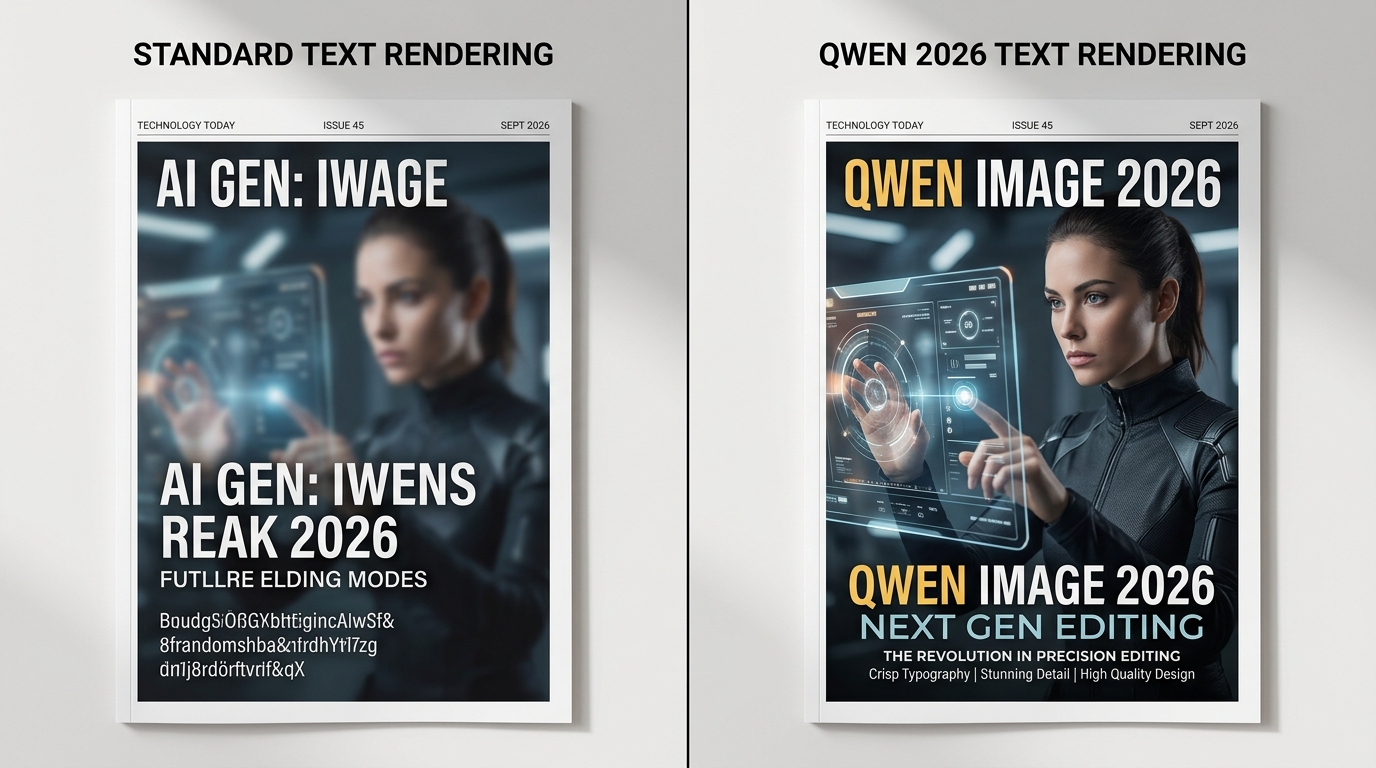
Visual Benchmark: Micro-Detail & Typography Comparison

Comparing character rendering accuracy, edge definition, and photorealistic texture retention under identical prompt conditions.

Side-by-Side Model Architecture and Typography Benchmark
Qwen 7B Multimodal Rendering:Sustains crisp typographic kerning, photorealistic specular reflections, and intricate micro-textures suitable for commercial marketing.
Nano Banana Edge Behavior:Produces images in sub-second speeds, but micro-details blur together with noticeable alphanumeric distortion on posters and packaging.

1. Architecture & Parameter Footprint: 7B Multimodal vs Edge Pruning

Understanding the architectural divergence in this edge vs foundation model comparison is fundamental for engineering teams. Qwen is built upon Alibaba's unified 7-billion parameter vision-language transformer. By sharing representations between visual tokens and textual semantics, the model preserves complex compositional logic, spatial prepositions, and fine-grained anatomical consistency.

Nano Banana, on the other hand, embraces extreme architectural pruning, distilling the diffusion backbone into roughly 1.2 billion parameters. This lightweight blueprint enables instant startup and minimal memory footprint, but sacrifices the parameter depth required for nuanced linguistic comprehension and complex lighting interactions.

2. Inference Latency & Hardware Costs: Cloud GPUs vs On-Device NPU

Latency and deployment expense represent decisive criteria when analyzing on-device edge generation against cloud GPU pipelines. Nano Banana excels when deployed on constrained edge devices—such as mobile smartphones, offline IoT terminals, or Apple Silicon NPUs—generating 512x512 drafts in under 700 milliseconds with minimal battery drain.

In contrast, Qwen is engineered for high-throughput cloud environments and workstation GPUs (such as RTX 4090 or A100). Utilizing FP8 quantization, it achieves 2-second inference at pristine 1024x1024 resolution. For digital creators without high-end GPUs, the web-based Qwen Image Editor provides free instant access without local hardware barriers.

3. Image Fidelity, Text Spelling & Complex Spatial Reasoning

When generating advertising banners, UI concept art, or product mockups, spelling fidelity within the synthesized image is critical. In side-by-side prompt testing, Qwen accurately renders multi-word bilingual slogans, numbers, and currency signs without character smearing.

Because Nano Banana operates with a smaller text encoder, it frequently scrambles multi-word slogans into unrecognizable pseudo-Latin glyphs. Creators requiring precise typography or brand signage should utilize the dedicated Qwen Image Generator to ensure publication-ready outputs.

4. Post-Production Inpainting & Production Readiness

A major workflow advantage highlighted in this technical review is conversational post-processing. Qwen natively supports conversational instruction editing: creators can upload an existing asset to the online AI inpainting editor and request localized changes (such as swapping apparel, shifting lighting, or adding accessories) while preserving surrounding geometry.

Nano Banana is strictly limited to text-to-image synthesis without native inpainting backbones. Attempting to modify a single object requires regenerating the entire canvas from scratch, resulting in severe character drift and wasted creative iterations.

Decision Guide: Which Model Fits Your Production Workflow?

Selecting in this generative model decision depends on your deployment constraints and quality threshold.

Choose Qwen if you require:

  • Flawless English and bilingual typography on posters, banners, and merchandise.
  • Conversational inpainting to modify localized elements without re-generating scenes.
  • Enterprise photorealism with accurate specular highlights and anatomical hands.
  • Free online browser testing and scalable cloud REST API integration.

Choose Nano Banana if you require:

  • Ultra-low latency generation (<1s) on budget mobile phones and offline terminals.
  • Minimal VRAM consumption (2GB to 4GB) on low-spec consumer hardware.
  • Casual concept doodling or real-time camera AR filter prototyping.
  • Embedded edge deployments without reliance on high-bandwidth cloud APIs.

Frequently Asked Questions: Qwen Image 2.1 vs Nano Banana

Clear answers addressing core architectural differences, hardware specs, typography capabilities, and edge deployment.

The foundational divergence lies in architectural capacity and deployment focus. Qwen is a full-scale 7-billion-parameter multimodal foundation model engineered for studio-grade image quality, flawless typography, and surgical instruction-based inpainting. Nano Banana is a heavily compressed edge model (~1.2B parameters) built specifically for ultra-low latency on mobile chips and devices with limited VRAM.
No. Commercial advertising, product mockups, and packaging design require precise typography, accurate brand logos, and predictable composition. Qwen excels in spelling words correctly and preserving fine textures, whereas Nano Banana lacks the parameter capacity to reliably generate legible text or complex multi-subject interactions.
Nano Banana runs locally on budget mobile hardware requiring only 2GB to 4GB of VRAM. For Qwen, community-quantized weights (including GGUF, FP8, and INT4 formats) enable smooth local deployment on consumer GPUs with 8GB to 12GB of VRAM. Alternatively, creators can use Qwen AI online without any local GPU burden.